AI audio and video engineering portfolio

A verifiable production pipeline for voice cloning, speech generation, and video creation.

This site documents two completed local applications: a multi-model IndexTTS2 speech workstation and an MP4 homepage video generator. The material is grounded in development notes, source code, and validation records so clients and AI agents can inspect the same technical facts.

  1. Structure the script
  2. Prepare an authorized voice reference
  3. Select a model and synthesize speech
  4. Compose images, captions, and audio
  5. Validate and publish

Completed applications

Two products. One complete content-production capability.

These are not concept mockups. Each case explains its input contract, call order, algorithms, fallback behavior, and validation criteria.

IndexTTS2 local speech workstation icon
Apple SiliconLocal-firstModel routing

IndexTTS2 multi-model speech workstation

A unified interface for IndexTTS 2.5, IndexTTS 2.0, OmniVoice, Fish Audio S2 Pro, and native VoiceStudio OmniVoice, with voice libraries, lazy loading, local ASR, expression controls, safe long-form chunking, and cancellable jobs.

Model calls and architecture
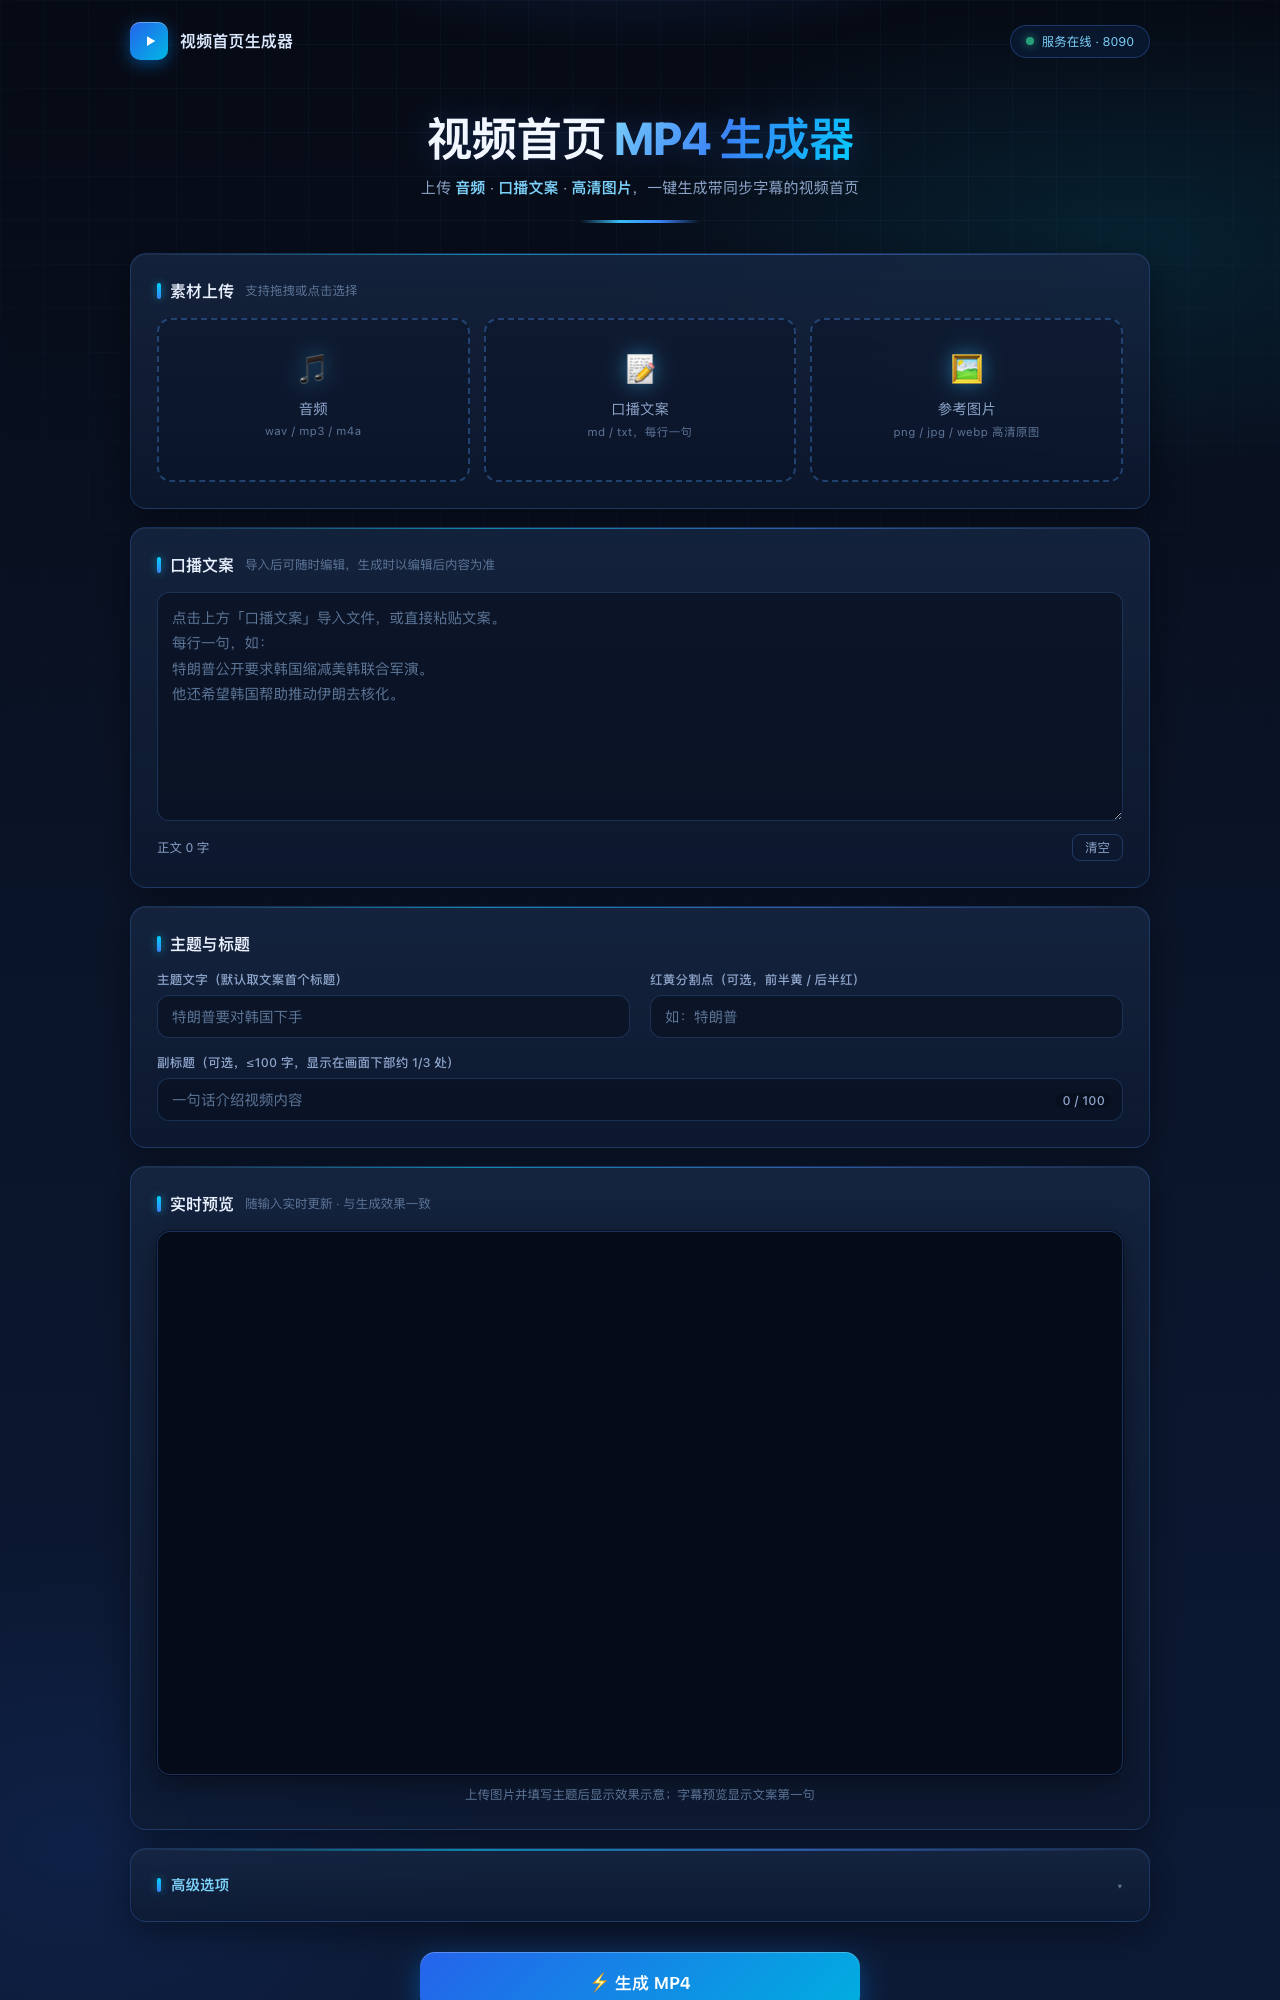
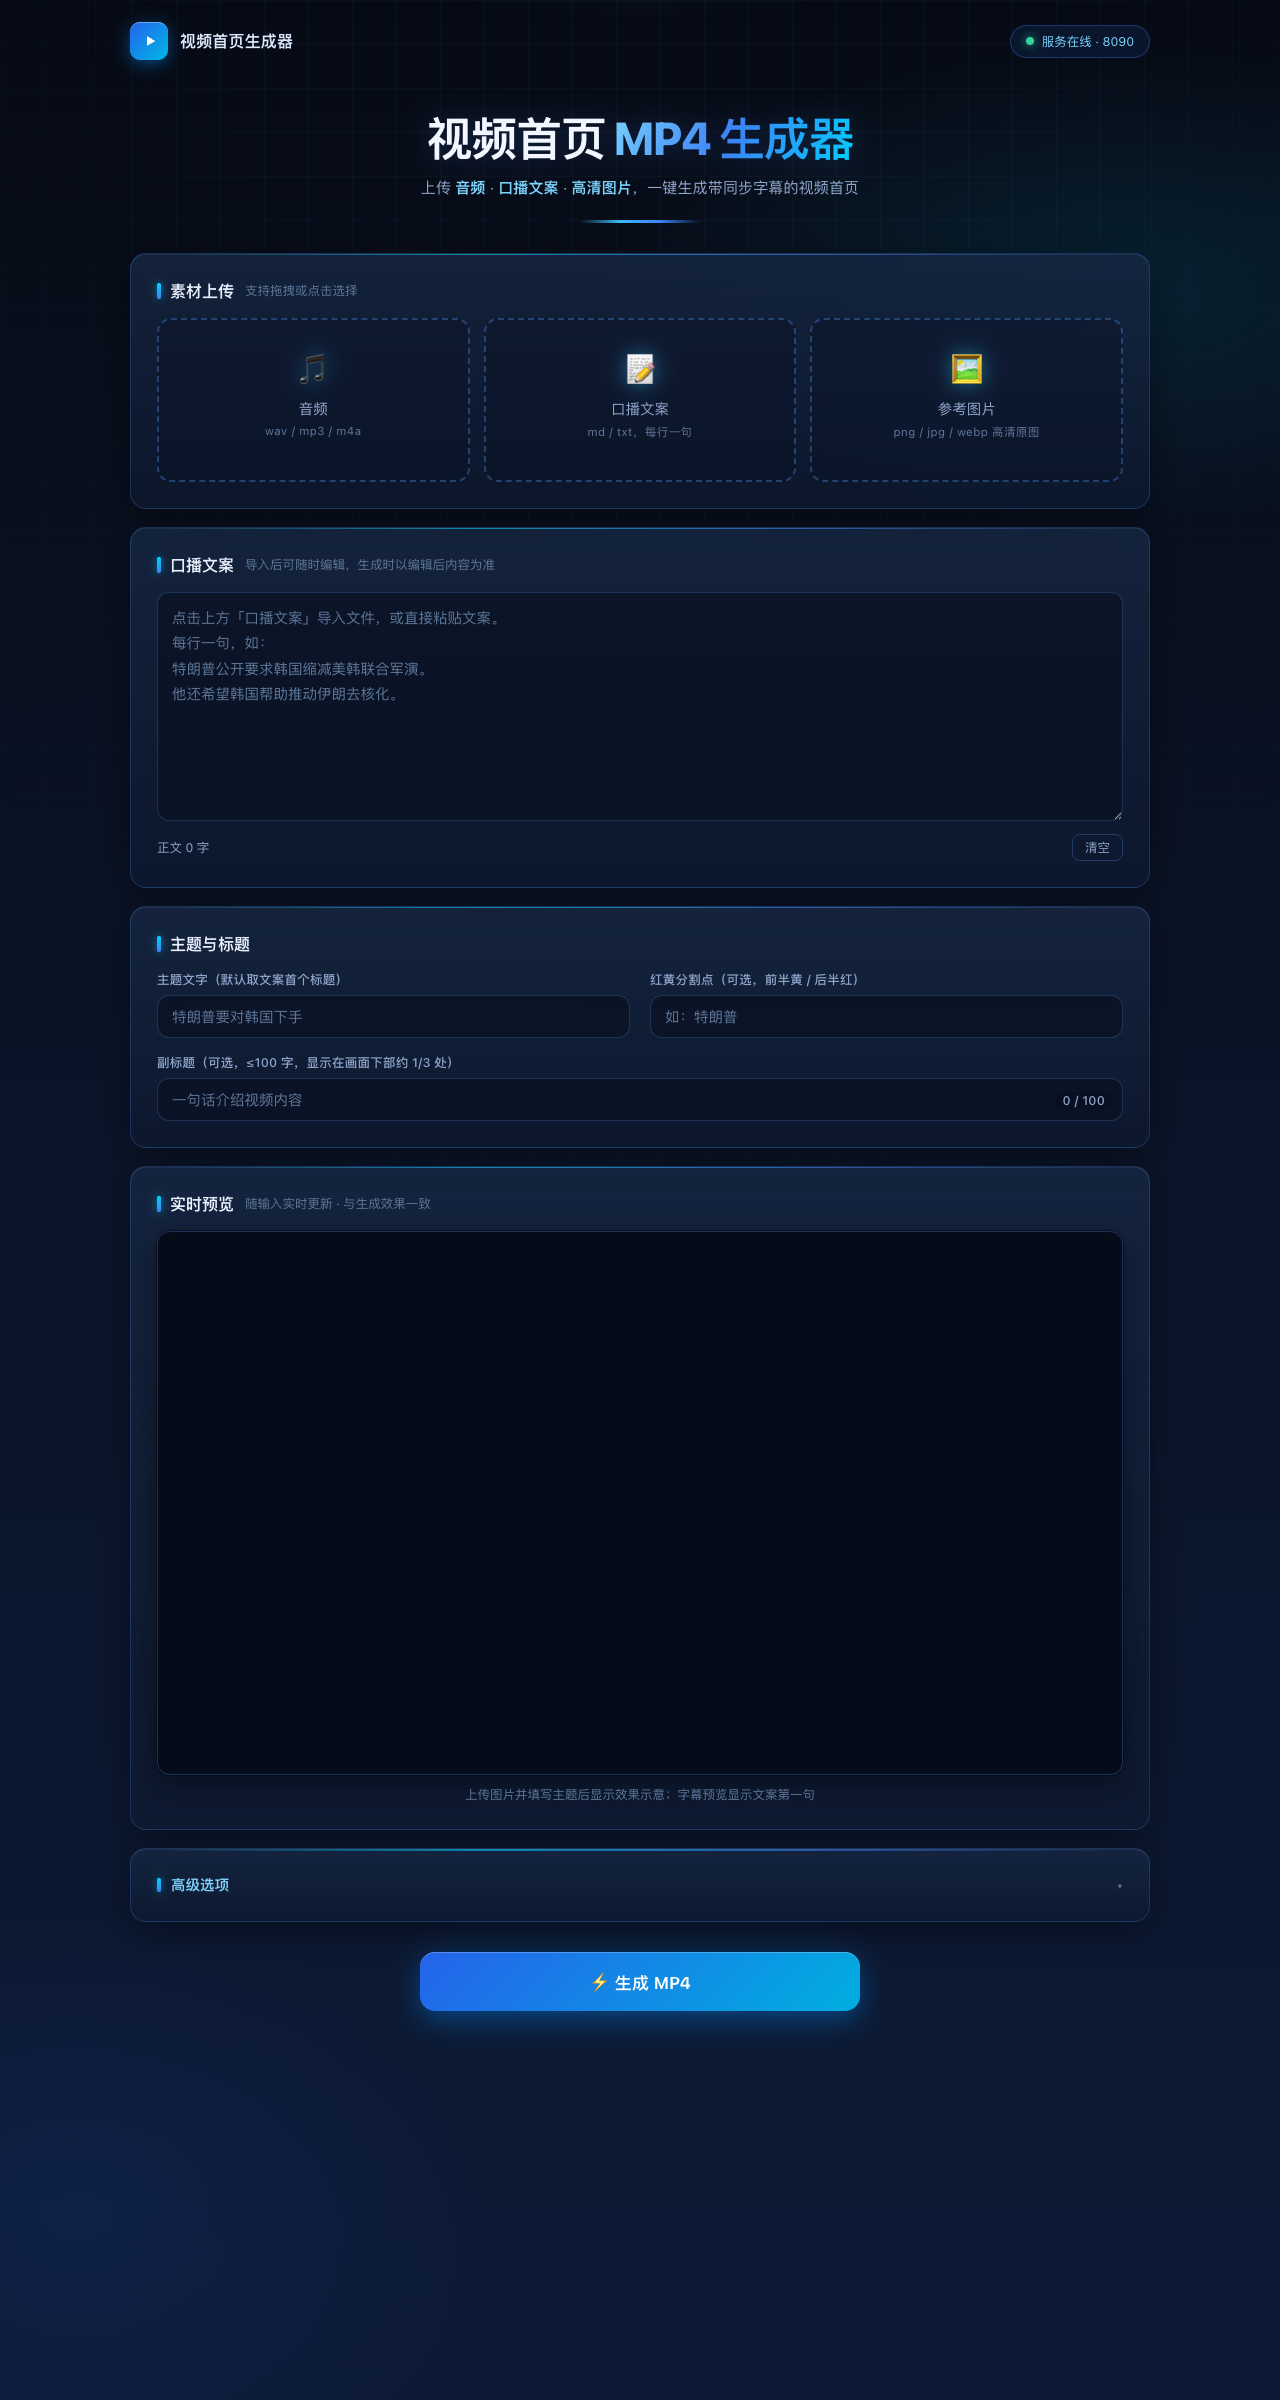
Production interface of the MP4 homepage video generator
FlaskFFmpegHardware accelerated

MP4 homepage video generator

Audio, narration text, and images become an H.264/AAC MP4 with an ordered image timeline, silence-based caption alignment, automatic orientation, asynchronous processing, persistent status, logs, results, and history.

Composition logic and steps

Product evidence

Interfaces, production states, and finished output from the completed applications.

These are not concept mockups. They show voice-library validation, the production video WebUI, reusable local voices, and a real long-form video homepage.

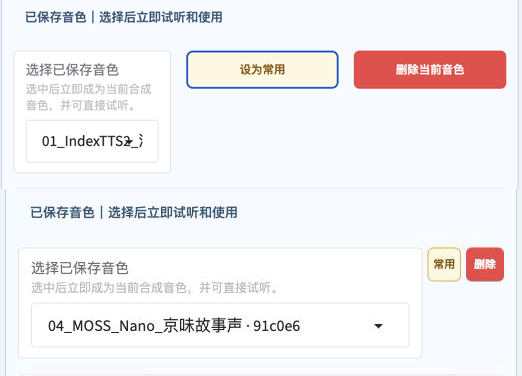
Before and after validation of the IndexTTS2 voice selector
01 / Voice-library validationLong names, favorites, preview, and deletion remain readable and distinct.
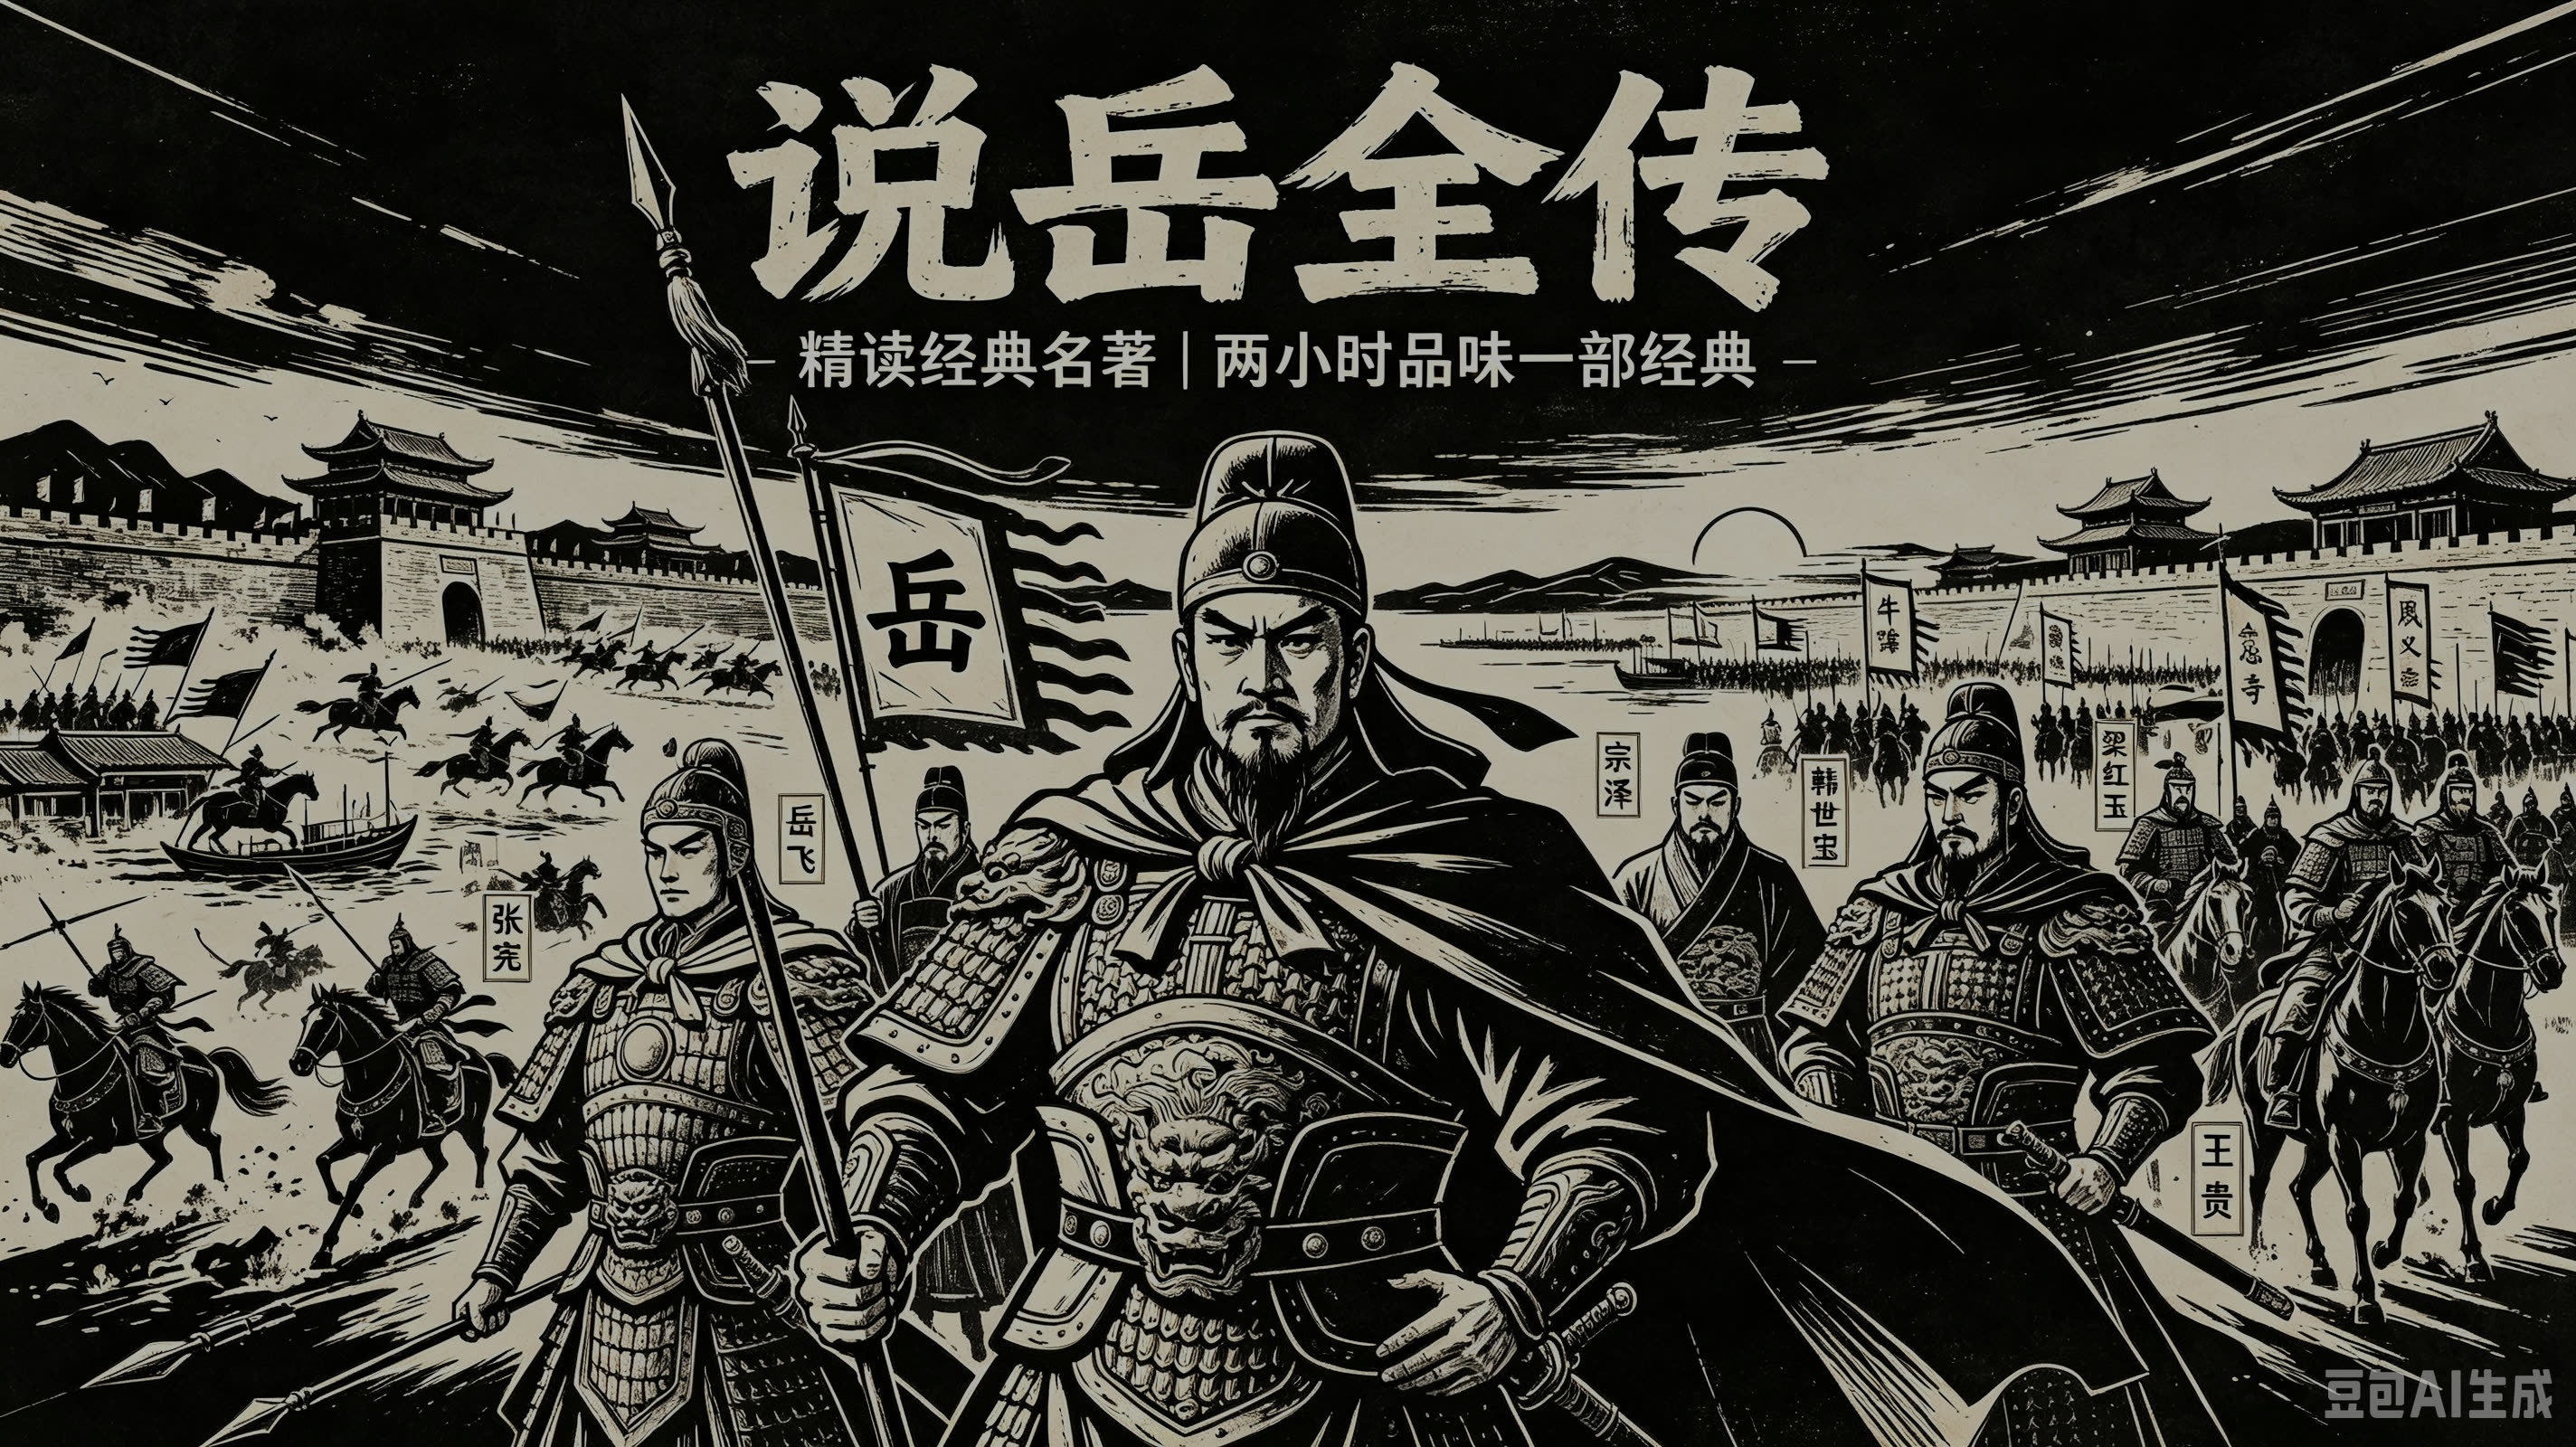
Literary video homepage generated for a long-form Romance of Yue Fei project
02 / Finished long-form homepageOutput from a real generation job whose source video runs about 2 hours 58 minutes.
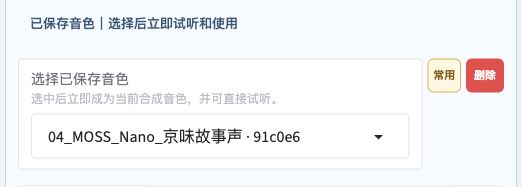
Local saved-voice library in the IndexTTS2 workstation
03 / Local voice managementSaved profiles support selection, preview, and repeatable batch work.
Complete MP4 homepage video generator interface
04 / Video production workstationAudio, text, images, titles, preview, and generation settings share one task path.

Play the speech sample Play the video sample

Deep technical archive

Every engineering decision from first input to final delivery.

The development record decomposes both applications into searchable operations. The model archive gives each engine an invocation contract, strengths, limitations, best-fit work, and licensing boundary.

Engineering logic

A usable product requires more than a successful model call.

The implemented layer covers model switching, unified memory pressure, task state, quality gates, fallbacks, and user operation cost.

01 / Input contract

Normalize unstable source material

Validate audio formats, duration, transcripts, image orientation, and script structure before inference begins.

02 / Model routing

Choose by output objective

Similarity, emotion vectors, text-designed voices, long-form work, and multi-speaker content take different paths.

03 / Resource control

Load large models on demand

Release the previous engine when switching and keep separate parameter profiles for each backend.

04 / Job control

Make long runs observable

Use safe chunks, progress and ETA updates, pause/cancel controls, and partial-result preservation.

05 / Media composition

Use absolute caption timing

Derive sentence boundaries from audio pauses, then compose visuals, captions, and audio at a fixed frame rate.

06 / Quality validation

Verify the deliverable

Check duration, sample rate, peaks, frame size, codecs, caption bounds, playback, and downloads.
Model matrix

One workstation, multiple engines selected by generation goal.

These five engine entries are present in the current local project. Model-weight licensing still needs separate review before commercial use.

EnginePrimary modeBest fitImplementation detail
IndexTTS 2.5Reference cloningChinese narration and long formMLX / 8-bit, default backend, cached voice conditioning
IndexTTS 2.0Clone + 8 emotionsExplicit emotion vectorsSeparate emotion type and strength controls
OmniVoice MLXClone / design / autoVoice design and expression presetsExact reference transcript alignment with local ASR fallback
Fish Audio S2 ProClone / auto / multi-speakerInline expression and multiple rolesSafe chunking, reference cache, 44.1 kHz output
VoiceStudio · OmniVoiceNative PyTorch/MPSNative-engine compatibilityIsolated subprocess, release on switch, three operating modes

Read the complete strengths, limitations, best-fit work, and engineering boundaries

Before and after validation evidence for the voice selector UI

Design and validation

Engineering quality includes making complex systems usable.

The workstation work also covers information density, readable long voice names, distinct destructive actions, and per-model parameter migration.

  • Layout proportions and overflow verified at a real browser size
  • Only controls supported by the active engine remain visible
  • Long jobs expose progress, pause, cancellation, and partial output
  • Model capabilities and commercial licensing boundaries stay explicit

Production scale

100,000 characters, 200,000 characters, and long video through recoverable orchestration.

There is no fixed business-level project ceiling. Large work is divided into chapter batches, model-safe segments, checkpoints, and resumable queues.

Audio projects

100k, 200k, and beyond

The current WebUI protects one task at 100,000 characters. Larger scripts become chapter batches; each segment is persisted and only failures are rerun.

Audio assembly

Chapters or full-volume delivery

Sample rate, loudness, silence, order, and naming are normalized before chapter or complete-project assembly.

Video duration

Driven by the audio track

The generator has no arbitrary minute cap. Multi-hour content can become one MP4 or an episodic set, subject to disk, encoding time, and platform constraints.

Commercial work

For teams that need the output, not another model experiment.

Custom delivery covers authorized voice cloning, local TTS workstations, 100,000+ character audio production, long-form video automation, and complete content pipelines.

Business email
wangdexin2008@126.com

Include approximate character count, target voice, video length, available visuals, and delivery formats.

Project inquiry

Submission opens your email application.